Cooling
Direct-to-Chip Cold Plates: How Liquid Gets to the Processor
Cold plates are the most common form of liquid cooling for AI servers. Here is how they work, from the metal block on the chip to the pumps in the room.

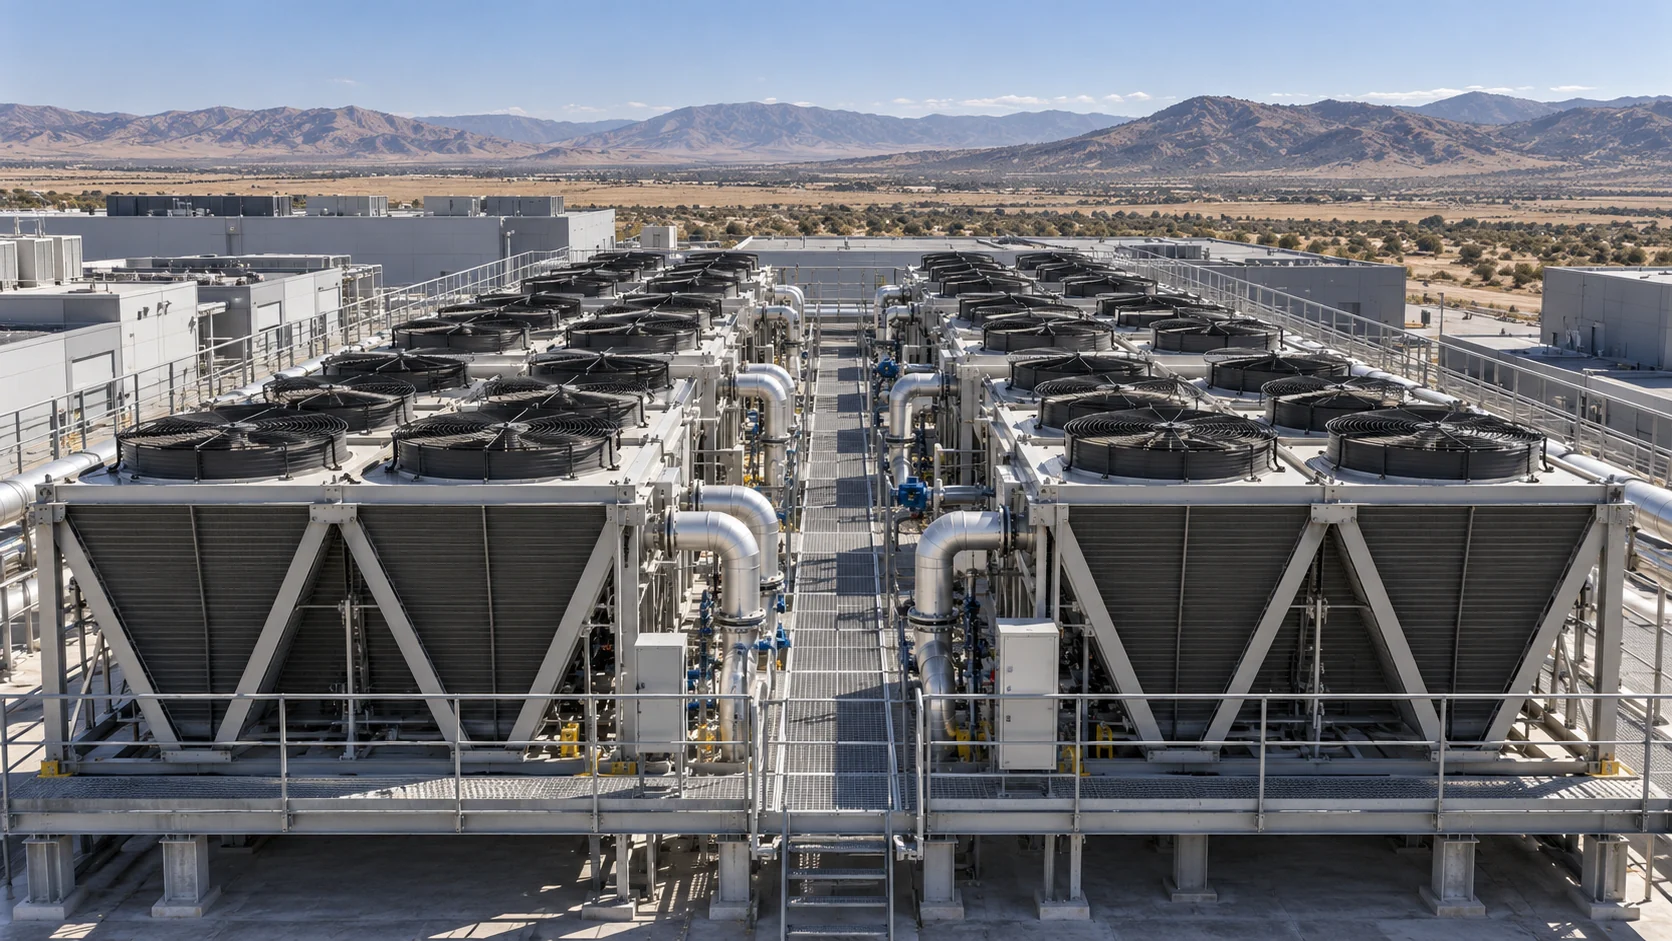
Of all the liquid cooling approaches in data centers, direct-to-chip cooling has become the most widely adopted for AI hardware. The idea is simple: instead of blowing air over a chip, put a liquid-cooled metal block right on top of it. The details, though, involve careful engineering at every step.
The cold plate itself
A cold plate is a flat block of highly conductive metal, usually copper, that mounts directly on a processor or accelerator, with a thin layer of thermal interface material in between to fill microscopic gaps. Inside the plate are fine channels or fins that coolant flows through. Heat travels from the chip into the metal and then into the moving liquid, which carries it away.
The internal channel design matters a great deal. Finer channels expose more metal surface to the coolant, improving heat transfer, but they also require more pumping pressure and can be more sensitive to particles in the fluid. Engineers balance these factors for each chip.
Following the loop
Coolant does not just sit in the plate. It travels through a series of loops:
- Server loop. Small tubes connect the cold plates inside a server to inlet and outlet fittings, often with quick-disconnect couplings so servers can be removed without draining the system.
- Rack manifolds. Vertical pipes in the rack distribute coolant to every server and collect the warmed fluid.
- Coolant distribution unit. Known as a CDU, this unit pumps the coolant, filters it, controls its temperature and transfers its heat to the building’s water system through a heat exchanger.
- Facility loop. The building’s water system carries the heat to outdoor equipment, such as dry coolers or cooling towers.
Keeping the server loop separate from the facility loop is important. It lets operators control the cleanliness, chemistry and pressure of the fluid near the electronics.
Single-phase and two-phase versions
Most cold plate systems are single-phase, meaning the coolant stays liquid the whole time. A common coolant is water mixed with an additive such as propylene glycol and corrosion inhibitors. Some designs are two-phase, using a special fluid that boils inside the cold plate. Boiling absorbs a lot of heat at a steady temperature, which can be very effective, but these systems are more specialized.
What cold plates do not cover
Cold plates typically cool the hottest components: processors, accelerators and sometimes memory or voltage regulators. Other parts, such as storage drives, network cards and power supplies, often still rely on fans. That is why many direct-to-chip deployments are described as capturing most, but not all, of a server’s heat in liquid. The remaining heat still needs some air cooling in the room.
Why operators choose it
Direct-to-chip cooling has several appeals. It fits standard rack formats, so it can be added without redesigning everything. It handles far higher heat loads than air. And because coolant can run relatively warm while still doing its job, the facility may be able to reject heat without energy-hungry refrigeration for much of the year.
The tradeoffs are new skills, new maintenance routines and careful attention to leak prevention and fluid quality. For many operators building for AI, those tradeoffs have become worth it.
Keeping the Loop Healthy
A direct-to-chip system is only as reliable as the fluid flowing through it. Because cold plate channels can be very fine, small problems in the coolant can grow into large ones. Operators typically focus on a handful of routine practices.
- Filtration. Filters in the coolant distribution unit capture particles that could otherwise lodge in cold plate channels and reduce flow.
- Chemistry checks. Coolant is sampled periodically to confirm that additives, such as corrosion inhibitors and biocides, remain at the right levels and that the fluid has not degraded.
- Material compatibility. Every wetted part, from tubes to fittings to cold plates, must be compatible with the fluid and with each other. Mixing certain metals in the same loop can encourage corrosion.
- Pressure and flow monitoring. Sensors track whether each rack and server is receiving the expected flow. A gradual drop can signal a clog; a sudden change can signal a leak or a failed pump.
- Commissioning and flushing. New loops are typically flushed and tested before hardware is connected, so manufacturing debris does not end up inside a cold plate.
Quick-disconnects and day-to-day service
Quick-disconnect couplings let technicians remove a server from the loop without draining it. Well-designed couplings seal on both sides as they separate, limiting spills to a drop or two. Staff are trained to connect and disconnect in a set order, inspect seals, and check for drips before closing up the rack. These small habits do a great deal to keep liquid where it belongs.
Warm Water and Why It Matters
One of the less obvious advantages of cold plates is that they can often work with relatively warm coolant. Because the metal plate sits directly on the chip, even coolant that would feel warm to the touch can still pull heat away effectively.
- Less refrigeration. If the facility can supply coolant at higher temperatures, it may be able to cool that water using outdoor air through dry coolers for much of the year, rather than running chillers.
- More useful waste heat. Warmer return water is easier to put to use, for example in building heating or other heat reuse projects.
- Wider site options. Higher supply temperatures can make efficient cooling possible in a broader range of climates.
The exact temperatures depend on the chip vendor’s specifications and the facility design, so operators follow manufacturer guidance closely.
Common Mistakes With Cold Plate Deployments
- Assuming liquid removes the need for air. As the article notes, a share of heat still goes into the room. Underestimating it can leave memory, drives or network gear running hot.
- Neglecting redundancy in the CDU. If a single pump or heat exchanger serves many racks, its failure affects all of them. Many designs include redundant pumps and multiple units.
- Skipping training. Technicians used to purely air-cooled servers need new procedures for handling, connecting and inspecting liquid-cooled hardware.
- Poor documentation. Clear labeling of supply and return lines, valve positions and fluid types prevents mistakes during maintenance.
Questions readers ask
Does the coolant touch the chip? No. In a cold plate system, the coolant stays inside the sealed metal plate and tubing. Only the plate touches the chip, through a thin interface layer.
What happens if a pump fails? Well-designed systems have backup pumps and alarms. If flow is lost, chips will heat quickly and throttle or shut down to protect themselves, so redundancy and fast response are essential.
Can existing servers be converted? Generally, cold plate cooling is designed into servers by the manufacturer. Retrofitting arbitrary hardware is uncommon and usually not supported.
Latest stories
View all


Cooling
A Coolant Distribution Unit Needs Its Own Power-Loss Story
A liquid-cooled server depends on more than the fluid in its cold plate. Pumps, valves, controls and the connection to the building’s heat-removal system all influence what happens when power is interrupted. The distribution unit belongs in that account.
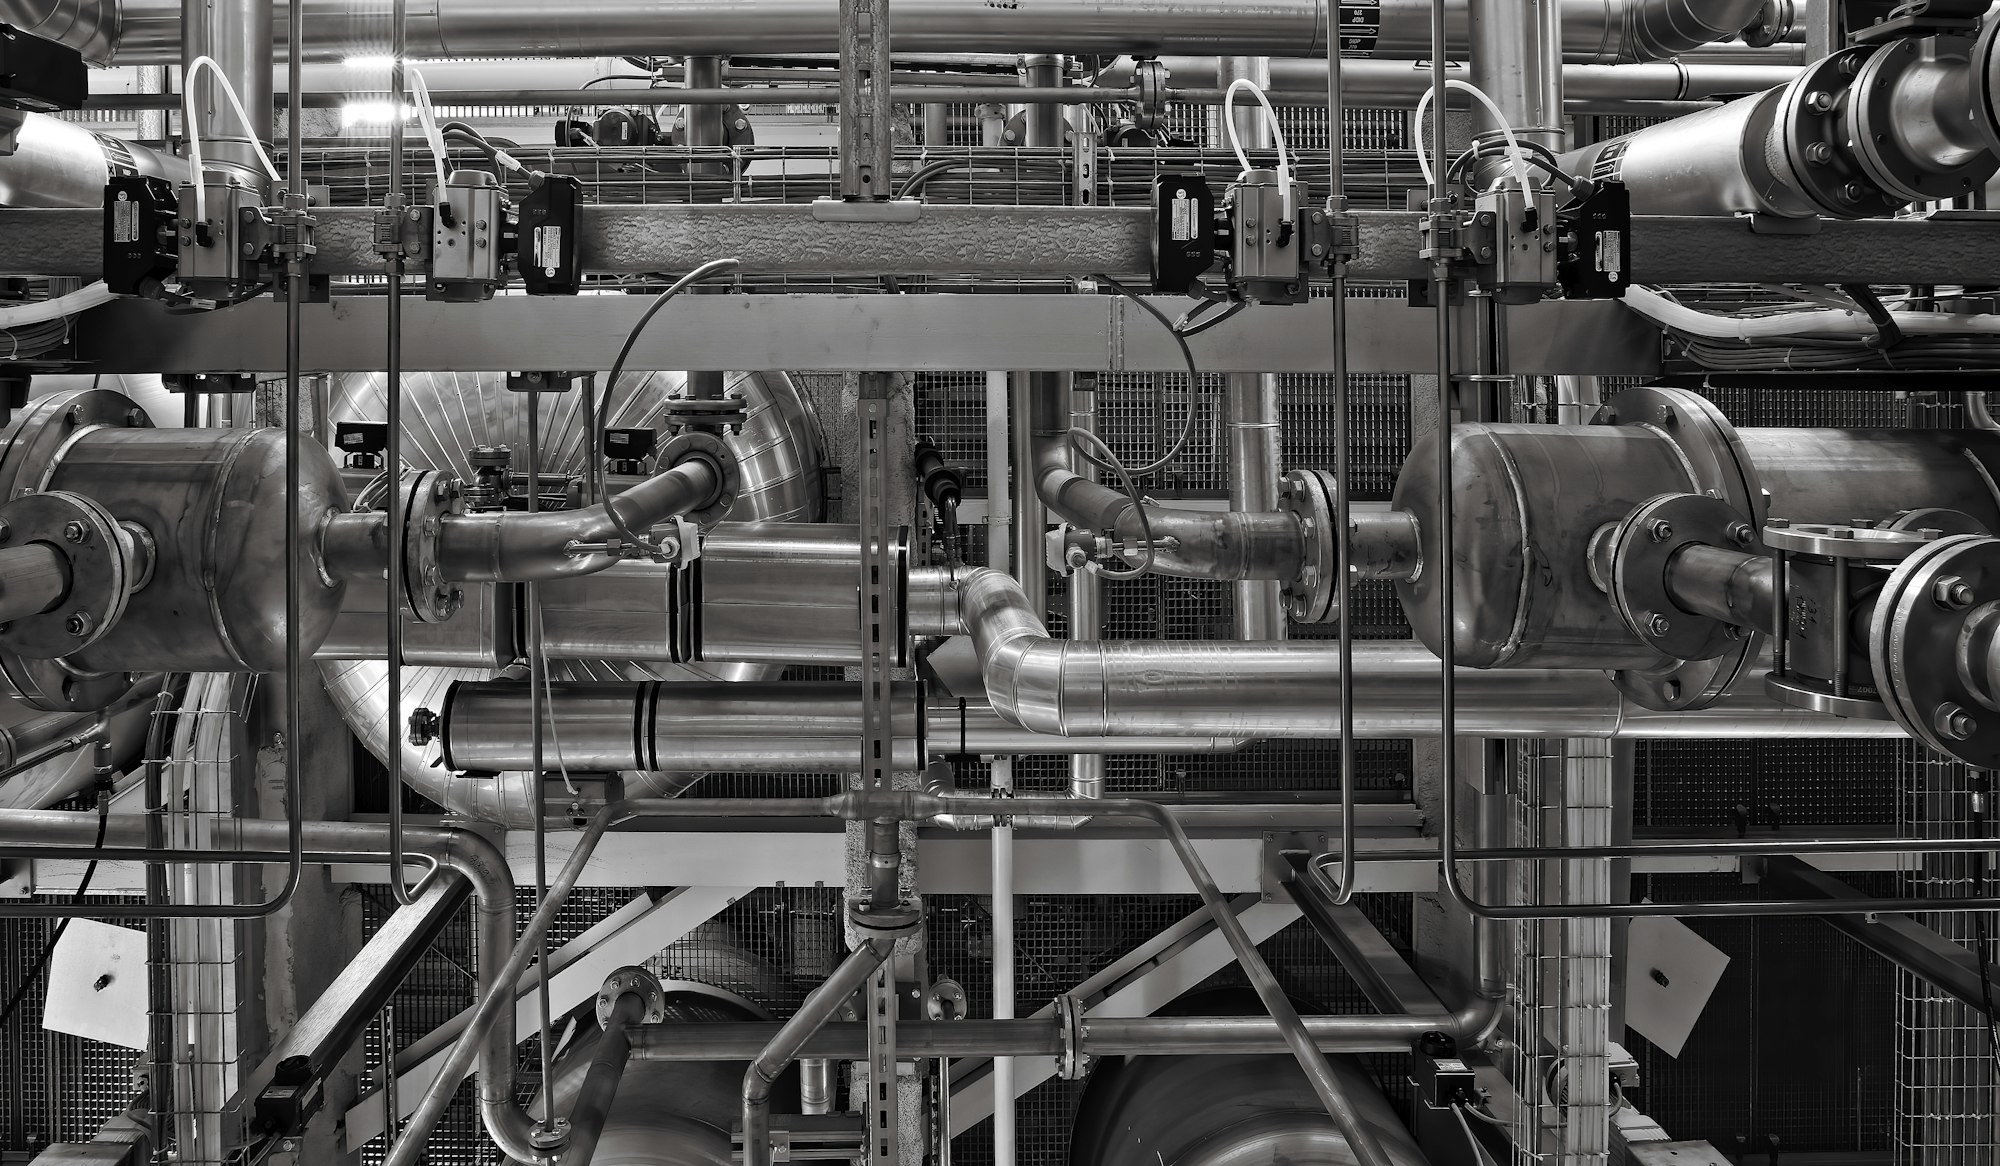
Photo: Ricardo Gomez Angel / Unsplash
A liquid-cooled server depends on more than the fluid in its cold plate. Pumps, valves, controls and the connection to the building's heat-removal system all influence what happens when power is interrupted. The distribution unit belongs in that account.
The operating distinction
A coolant distribution unit transfers heat between circuits and helps manage conditions on the equipment side. Its exact role varies by design. If circulation or control is interrupted, the server's thermal response depends on the equipment, load and supporting arrangements rather than on the word liquid alone.
The cooling account should also describe what is observed during an interruption. A pump may be energized while a required flow condition is not established. Conversely, a brief control notification may not mean that heat removal has already failed. The instrumentation and sequence matter.
A practical example
Consider a hypothetical hall where servers remain electrically supported during a short interruption. If the associated cooling equipment does not share that support, the useful operating window may be limited by heat removal. Testing should connect those systems rather than evaluate them as unrelated purchases.
Questions worth asking
A power-transfer account should keep cooling behavior within view. The server, circulation equipment and controls form a connected operating story, even when different suppliers describe or test their own components separately during acceptance.
- Which pumps and controls remain powered during a transfer event?
- What heat-removal path stays available while normal service is interrupted?
- Which integrated test demonstrates the intended equipment response?
What the evidence supports
There is no universal safe ride-through period to infer from this description. Equipment limits and site conditions differ. A credible account names the tested configuration and explains the response sequence, including what the system does when conditions approach an operating limit.
An integrated discussion can connect electrical support, coolant circulation and equipment protection without assuming a single universal design. The evidence should state what was operated and what was measured. That keeps a component supplier's valid performance description from becoming an unsupported facility-wide assurance. It also helps readers understand why electrical and cooling teams need a shared account of a transfer event rather than separate success statements.
Follow the heat path and the control path through the interruption, not only the electrical supply to the servers.
Quick check
How much did you catch? Tap a question to see the answer.
1. What else matters besides the fluid in the cold plate?
Answer: Pumps, valves, controls and the link to the building’s heat-removal system.
2. Does an energized pump guarantee flow?
Answer: No. Instrumentation and sequence matter.
3. What can limit the operating window during an outage?
Answer: Heat removal, if the cooling equipment doesn’t share the servers’ power support.
The Pieces of a Liquid Cooling Power Story
A complete account of what happens during a power interruption in a liquid-cooled hall usually involves several systems that may have been specified, purchased and tested by different teams. In general terms, the pieces include:
- The servers and their power supplies. These may be supported by uninterruptible power during a transfer event.
- The coolant distribution unit. Its pumps, valves, sensors and controller move and regulate coolant on the equipment side and exchange heat with the facility side.
- The facility water or heat-rejection system. Chillers, dry coolers, cooling towers or other equipment remove heat from the building loop.
- Controls and monitoring. Building management and equipment controllers decide how each system responds and report conditions to operators.
- Air-side cooling. Many liquid-cooled racks still reject some heat to air, so room cooling may remain part of the picture.
- Thermal mass. The volume of coolant in the loops and the heat capacity of the equipment influence how quickly temperatures change once heat removal is reduced.
Each element may have its own power support arrangement. The useful question is how they behave together in a specific design.
Structuring an Integrated Discussion
The outline below describes how electrical and mechanical teams can build a shared account. The technical detail belongs to qualified engineers and the site’s procedures.
- Describe the event. Name the interruption being considered, such as a utility loss followed by generator start, or a transfer between sources.
- List power support for each element. Identify which pumps, controllers and cooling equipment are supported, and for how long.
- Trace the sequence. Describe what each system does in order, from the first loss of normal power to the return of full cooling.
- Identify the limiting element. Determine which part of the chain sets the practical operating window for the equipment.
- Describe protective responses. State what equipment does if temperatures approach their limits, including any throttling or controlled shutdown.
- Test the integrated chain. Demonstrate the sequence in a defined configuration and record what was measured.
Common mistakes
One mistake is assuming that because servers stay powered, cooling must be adequate. Another is accepting separate component tests as proof of integrated behavior. A third is overlooking control restarts, where equipment regains power but takes time to resume its intended operating mode. A fourth is extending a test result from one load level to another without considering how a heavier load changes the thermal response.
What This Means for Readers Following AI Infrastructure
As high-density computing pushes more facilities toward liquid cooling, the conversation about resilience broadens. A reliable electrical design is necessary, but it is not the whole story. Readers looking at announcements of new liquid-cooled capacity can reasonably ask whether the provider describes an integrated test of power and cooling together. A thoughtful answer suggests that the teams responsible for each have worked from the same account.
The heat does not stop arriving when the power transfers. Something has to keep carrying it away.
Questions Readers Ask
Does liquid cooling make a hall more or less sensitive to power interruptions?
It depends on the design, the coolant volume, the load and how the supporting equipment is powered. There is no single answer for all installations.
Why would a pump be running while flow is inadequate?
A valve position, an air pocket, a control setting or a blockage can prevent the intended flow even when the pump is energized.
Who usually owns the integrated test?
Often the commissioning team working with the owner, with input from equipment suppliers and both electrical and mechanical engineers.
AI infrastructure explainers and news on iPhone, iPad and Apple Watch.
Cooling
Cold Weather Can Reach Cooling Equipment Through Small Exposed Components
Large cooling equipment tends to dominate photographs, but winter exposure can concentrate in a smaller pipe, instrument connection or idle branch. A system’s overall size does not identify its most vulnerable point when outdoor conditions change.
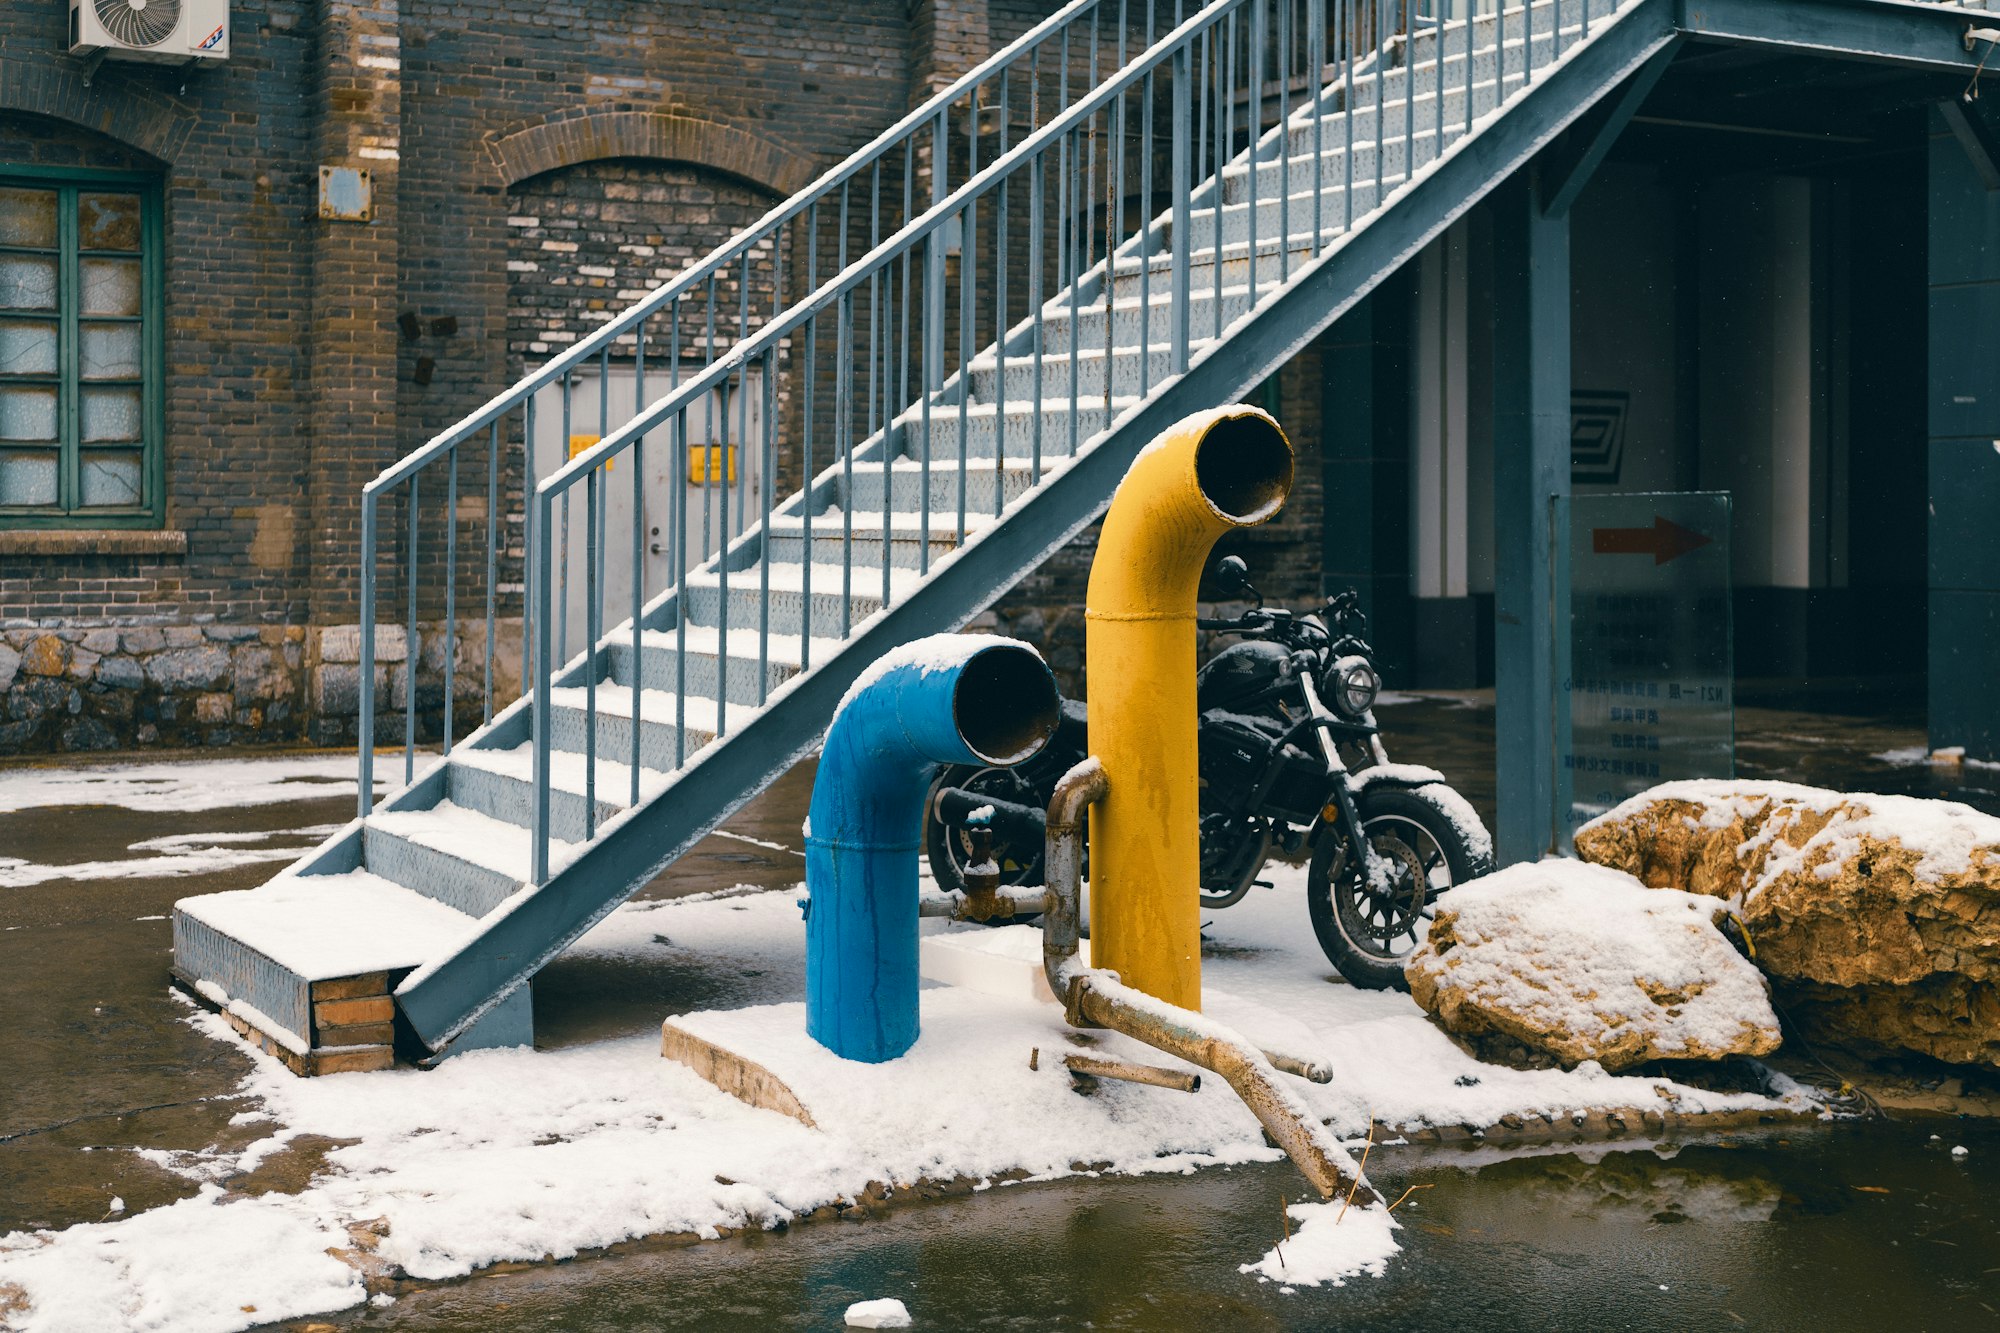
Photo: X F / Unsplash
Large cooling equipment tends to dominate photographs, but winter exposure can concentrate in a smaller pipe, instrument connection or idle branch. A system's overall size does not identify its most vulnerable point when outdoor conditions change.
The operating distinction
Water-containing equipment and associated controls need arrangements appropriate to their environment and design. Exposure can differ between an operating circuit and an isolated section. Insulation, protection systems and operating procedures also need inspection and maintenance; their presence on a drawing does not establish their current condition.
Seasonal checks should include changes made since the last cold period. A repaired pipe route, a relocated instrument or an altered enclosure can introduce a new exposure even when the equipment list appears unchanged. The installed state deserves a fresh comparison with its documentation.
A practical example
Picture an outdoor assembly with a protected main loop and a small branch left unused after maintenance. The branch may face a different thermal condition from the flowing circuit. A winter review should follow the actual installed arrangement, including temporary changes, rather than only the central equipment list.
Questions worth asking
The winter review should connect environmental exposure with the component's current operating state. A protective measure that exists on the original design still needs an owner and a relevant condition check after later changes.
- Which small or idle sections face a different outdoor exposure?
- Who checks the condition of installed freeze-protection measures?
- Have maintenance changes altered the original winter operating arrangement?
What the evidence supports
This is not a field instruction for changing coolant mixtures or electrical protection. Those choices depend on equipment requirements and qualified site procedures. The reporting question is whether the organization has identified exposed components and assigned responsibility for checking the protective measures.
It also helps to distinguish prevention from detection. Protective arrangements address the condition, while an alarm may only tell someone that a limit has been approached or crossed. Neither should be assumed to replace the other. A clear review names what each measure is intended to do, who verifies it and how the site recognizes a loss of protection before treating the winter arrangement as ready.
Winter readiness should follow the real system down to its exposed details, not stop at the main plant.
Quick check
How much did you catch? Tap a question to see the answer.
1. Where can winter exposure concentrate?
Answer: In a small pipe, instrument connection or idle branch.
2. Does insulation on a drawing prove its condition?
Answer: No. It needs inspection and maintenance.
3. What should seasonal checks include?
Answer: Changes made since the last cold period.
Where Small Exposures Tend to Appear
Winter reviews often concentrate on the largest pieces of equipment because they are the most visible and the most expensive. The smaller details can deserve as much attention, since they may have less thermal mass, less flow and less frequent inspection. In general terms, the places worth looking include:
- Instrument connections and sensing lines. Small-diameter tubing that feeds a gauge or transmitter may sit outside the insulated envelope of the main pipe.
- Drains, vents and test points. These are often closed and still for long periods, which can leave them exposed to outdoor conditions.
- Idle or isolated branches. Sections valved off for maintenance or future use may no longer share the flow and temperature of the operating circuit.
- Penetrations and enclosure gaps. Where a pipe passes through a wall, roof or cabinet, damaged seals or missing insulation can concentrate exposure.
- Recently repaired sections. A replacement component may not have received the same insulation or protective arrangement as the original.
- Control and heat-tracing circuits. Protective systems themselves depend on power, settings and working sensors that need confirmation.
A Seasonal Review in Practical Steps
A winter readiness review can be organized as a short sequence that follows the installed system rather than the original drawing set. The detailed technical work belongs to qualified site personnel; the outline below describes how the review is structured.
- Collect changes since the last cold season. Gather records of repairs, relocations, temporary arrangements and enclosure changes.
- Walk the installed arrangement. Compare what is physically present with the documentation, paying attention to small components and idle sections.
- Confirm the protective measures. Check that each intended protection is present, in working condition and assigned to an owner.
- Confirm detection. Verify that alarms tied to winter conditions reach the right people and that the related sensors are reporting.
- Record open items. Note anything that could not be confirmed, with an owner and a target date before the coldest part of the season.
Common mistakes
One mistake is treating last year’s review as still valid when the installed system has changed. Another is assuming that insulation shown on a drawing is intact in the field, despite weather, maintenance traffic and age. A third is relying on detection alone, so that the first sign of a problem is an alarm after protection has already been lost. A fourth is leaving temporary arrangements in place after the work that required them has finished, without anyone noting the change.
What This Means for Readers Following Infrastructure
Seasonal operating risk is one of the quieter factors behind data center reliability. Facilities in colder regions can benefit from outdoor air for cooling during much of the year, which is often discussed as an efficiency advantage. The same environment asks for careful attention to exposure in winter. A provider’s ability to describe its seasonal procedures in general terms, without revealing sensitive details, is a reasonable indicator that the topic has an owner.
The largest machine on the site is rarely the only thing the weather can reach.
This explanation is general education. It is not a field procedure, and coolant, electrical and protection choices belong to qualified specialists following the equipment requirements and site procedures.
Questions Readers Ask
Why would a small pipe be more exposed than a large one?
Smaller components generally hold less fluid and may have less flow, so they can respond to outdoor temperatures more quickly than a large, actively circulating loop.
Is an alarm enough to protect against winter damage?
An alarm tells someone that a condition is developing. It does not by itself prevent the condition, so prevention and detection are usually reviewed together.
When should a winter review take place?
Ideally before the first sustained cold period, with enough time to resolve the items it identifies.
Do temporary maintenance arrangements matter in winter?
Yes. An isolated or bypassed section may face conditions the original design did not anticipate, so temporary states deserve their own check.
AI infrastructure explainers and news on iPhone, iPad and Apple Watch.
Cooling
Cooling Alarms Need an Owner After the Day Shift Leaves
An alarm is a request for a decision, not a cooling system by itself. During an evening or holiday shift, the difference between a useful alert and background noise is often the clarity of ownership and escalation.
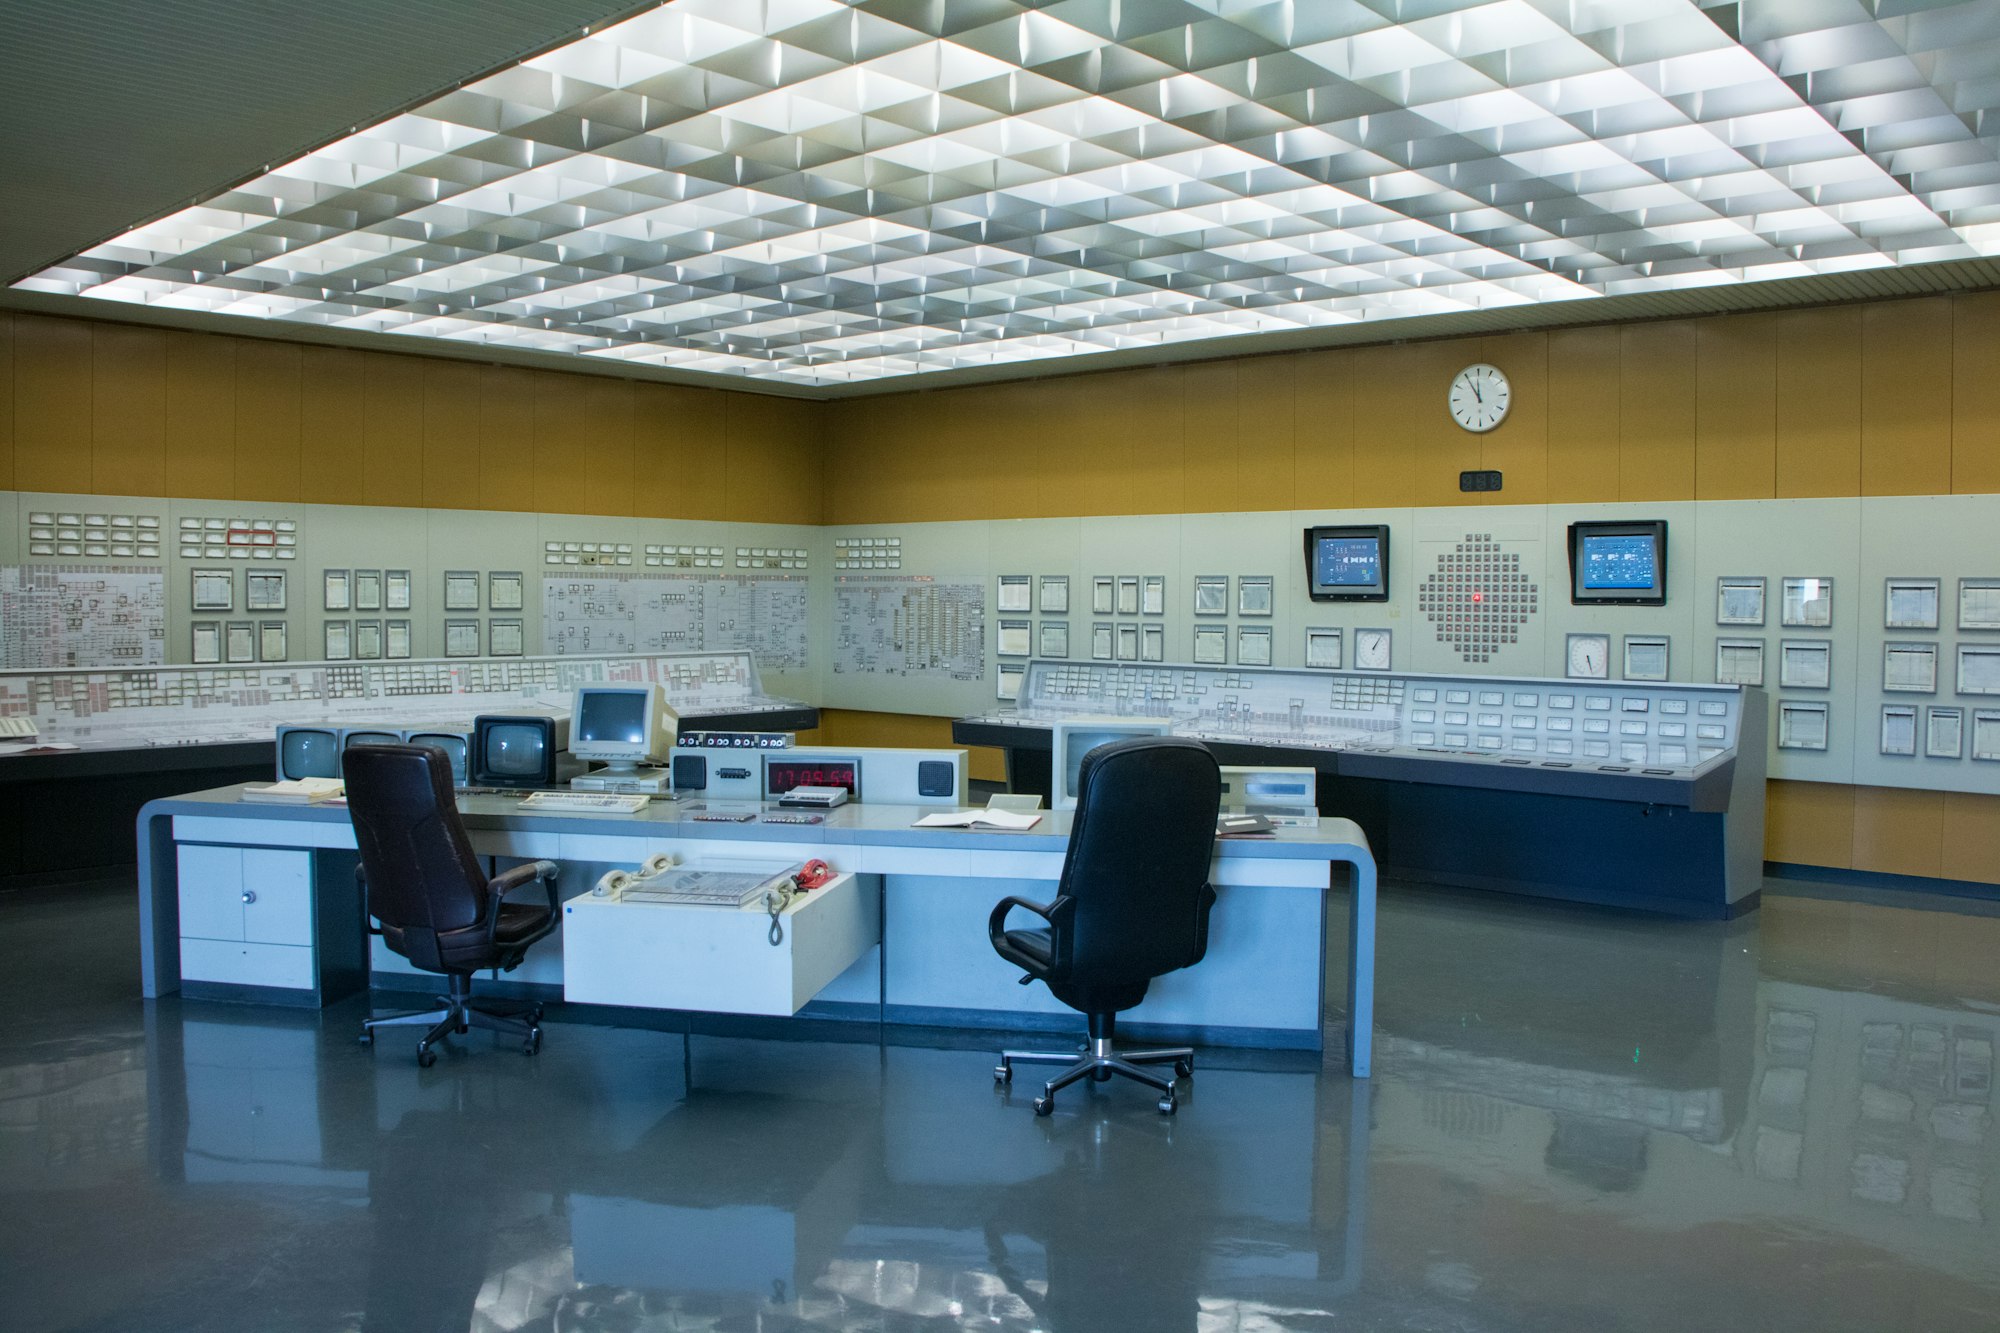
Photo: Miha Meglic / Unsplash
An alarm is a request for a decision, not a cooling system by itself. During an evening or holiday shift, the difference between a useful alert and background noise is often the clarity of ownership and escalation.
The operating distinction
Sensors can report a temperature, a leak indication, a pump state or a communication fault. Those signals do not all require the same response. A warning may permit investigation, while another condition demands immediate operational attention under the site's procedures. The person receiving it needs enough context to tell them apart.
Alert ownership should survive changes in staffing and equipment names. A clear notification can identify a meaningful location, explain the current operating mode and point to the applicable response record. That context reduces the effort needed to establish what the message refers to.
A practical example
Picture a hypothetical control room receiving a high-temperature alert from an isolated sensor. The response should connect the location, affected equipment and related readings. A message that contains only a device number forces the operator to reconstruct the system while the condition is changing.
Questions worth asking
An alert becomes actionable when its recipient can connect the message to equipment, context and responsibility. Reviewing that connection is more informative than comparing the total number of warnings generated by different systems.
- Who receives the alert when the primary contact is unavailable?
- Which related readings help distinguish a sensor issue from overheating?
- How is the response recorded for the next shift?
What the evidence supports
More alerts do not automatically improve coverage. Repeated low-value notifications can obscure a developing fault. Suppressing every noisy signal can create a different blind spot. Reviews should distinguish an equipment problem from a monitoring configuration problem, with changes controlled and recorded.
An alarm review can examine a small set of real events rather than debate the total number of sensors. Did somebody receive each notification, understand it and record the result? Were there avoidable repeats or gaps in responsibility? This makes the discussion about the operation of the response chain, while leaving the technical setpoints and equipment interventions to the site's authorized specialists and procedures.
A dependable alarm chain connects a meaningful condition to an informed person with a clear next step.
Quick check
How much did you catch? Tap a question to see the answer.
1. What is an alarm, according to the article?
Answer: A request for a decision, not a cooling system by itself.
2. What makes an alert useful after hours?
Answer: Clear ownership and escalation.
3. What context should a notification carry?
Answer: A meaningful location, the operating mode and a link to the response record.
Building an Escalation Path That Works at Night
An escalation path is easy to describe during a planning meeting and harder to rely on at the end of a long evening. The practical test is whether a person who did not write the procedure can follow it under pressure. A few design choices make that more likely.
- Name roles before names. Assign responsibility to a role such as on-shift operator or on-call mechanical lead, then map people to roles in a roster that changes with the schedule. Procedures tied to individual names go stale quickly.
- Define a response window for each level. State how long the first recipient has to acknowledge an alert before it moves to the next level. Without a stated window, an unanswered alert can sit in silence.
- Provide a working backup. Every escalation level needs a second contact who is genuinely available, not simply listed.
- Separate acknowledgment from resolution. Acknowledging an alert means someone owns it. It does not mean the condition is resolved, and the record should reflect both states.
- Test the path. Send a planned test alert during an evening shift and confirm that it reaches the right person, that the contact details work and that the response record is completed.
What a useful alert message contains
A message that can be acted on quickly usually includes the equipment or area in plain terms, the reading and its normal range, the time the condition began, any related readings, the current operating mode and a pointer to the relevant procedure. Those details let the recipient decide whether to investigate, escalate or follow an immediate response step.
Common Weak Points in After-Hours Coverage
Most failures in an alarm chain are not dramatic. They are small gaps that line up at the wrong moment.
- Stale contact information. A phone number or group address that changed during a reorganization can silently break the chain.
- Alert fatigue. When recipients see the same low-value warning repeatedly, they may learn to dismiss it, including on the night it matters.
- Ambiguous equipment labels. A device identifier that means something to the commissioning team may mean nothing to a newer operator.
- Unrecorded handovers. If the day shift was watching a developing condition, the evening shift needs to know that before the next alert arrives.
- Silent monitoring failures. A sensor that stops reporting may generate no alarm at all unless loss of communication is itself treated as an alert.
A short shift handover checklist
- Open alerts and their current owners
- Equipment in a non-standard operating mode
- Planned work scheduled during the coming shift
- Sensors or monitoring feeds known to be unreliable
- Any temporary changes to escalation contacts
Why This Matters Beyond the Control Room
For readers following data center operators and the businesses that rely on them, alarm ownership is part of what sits behind a reliability claim. A facility with excellent equipment can still have a weak response chain, and a well-organized response chain can limit the effect of an ordinary equipment fault. When a provider discusses uptime, the operating practices behind the number are as relevant as the hardware.
This is general explanation of operating practice. Specific setpoints, response steps and safety procedures belong to each site’s qualified specialists.
Questions Readers Ask
Should every alert wake someone up?
No. Alerts are usually tiered so that conditions requiring immediate attention reach a person right away, while informational warnings are reviewed during normal hours. The tiering itself should be reviewed and controlled.
How often should an escalation path be tested?
Often enough that changes in staff, contacts and tools are caught. Many teams test after any significant roster or system change as well as on a regular schedule.
What is the difference between a sensor fault and an equipment fault?
A sensor fault means the measurement is unreliable. An equipment fault means the system itself is not performing. Related readings from nearby sensors often help tell the two apart.
Who should own alarm configuration changes?
A named role with authority to approve them, with each change recorded so the next shift understands why an alert behaves differently.
AI infrastructure explainers and news on iPhone, iPad and Apple Watch.

A Coolant Distribution Unit Needs Its Own Power-Loss Story

The Control Plane Can Be a Shared Dependency Across Separate Systems

A Maintenance Window Changes the Meaning of Redundancy

Remote Support Depends on More Than a Telephone Number

Transformer Lead Times Are Becoming a Data-Center Schedule Risk

Gas Turbines on Data-Center Campuses

Water Use and Dry Coolers: The Tradeoff AI Sites Cannot Avoid

Battery Storage at AI Sites
A Coolant Distribution Unit Needs Its Own Power-Loss Story
The Control Plane Can Be a Shared Dependency Across Separate Systems
A Maintenance Window Changes the Meaning of Redundancy
Remote Support Depends on More Than a Telephone Number
-
 Power & Grid1 month ago
Transformer Lead Times Are Becoming a Data-Center Schedule Risk
-
 Power & Grid1 month ago
Gas Turbines on Data-Center Campuses
-
 Cooling2 months ago
Water Use and Dry Coolers: The Tradeoff AI Sites Cannot Avoid
-
 Power & Grid1 month ago
Battery Storage at AI Sites
-

 Compute & Silicon1 month ago
GPU Supply Chains: How AI Hardware Gets Made, Moved, and Bottlenecked
-

 Power & Grid4 weeks ago
FERC’s Large-Load Orders: The November 16 Grid Deadline Behind the AI Build-Out
-

 Capital & Backlog4 weeks ago
AI Infrastructure’s Rough Week: Chips Fall 6.7% as Meta Lifts Capex Floor
-

 Cooling4 weeks ago
Liquid-Cooling Leak Detection and Reliability